•
10 min read
CAREBench: An Assay for Context-Aware Classification of Sensitive Health Data
An open research framework that tests whether language models change their sensitive-data judgments when patient context is added, and whether those changes match the shifts physicians show.
Clinical LLMs
Sensitive Health Data
Data Segmentation
LLM Evaluation
Research Tooling
•
3 min read
What 'Hallucination' Actually Means in Clinical LLMs (And How to Measure It)
Why standard NLP benchmark metrics fail to quantify clinical hallucination risk, and how a domain-specific error taxonomy bridges model evaluation and bedside safety.
Clinical LLMs
AI Safety
LLM Evaluation
Evidence Grounding
•
3 min read
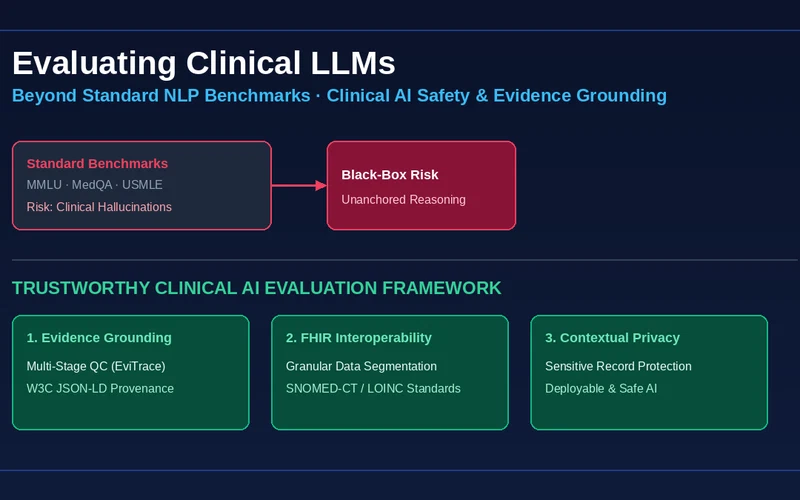
Evaluating Clinical LLMs: Beyond Standard NLP Benchmarks
Why general LLM benchmarks like MMLU or GSM8K fall short in medicine, and how evidence grounding, hallucination bounds, and FHIR interoperability redefine clinical AI safety.
Clinical LLMs
AI Safety
Evidence Grounding
Health Informatics
Clinical LLMs
Sensitive Health Data
Data Segmentation
Early Evidence for Context-Aware Large Language Models (LLMs) in Sensitive Health Data Classification
Presented early evidence that context-aware LLMs can classify sensitive health data for consent-driven record sharing.
Clinical LLMs
Sensitive Health Data